JavaScript Passport Scanner: MRZ, OCR, and Portrait Extraction
A passport data page carries three different kinds of information, and each one needs a different engine. The machine readable zone is a rigid grid — two 44-character lines whose every position is defined by ICAO 9303, which is why it can be read exactly and then parsed into named fields. The visual zone is free-form text that changes with every issuing country. The portrait is an image region, not text at all.
This guide builds all three in the browser. Dynamsoft Capture Vision 3.6.5000 handles the MRZ: a single capture(image, "ReadMRZ") call returns the two MRZ lines as a TextLineResultItem and the parsed fields as a ParsedResultItem in the same result object, so there is no second parsing pass. PaddleOCR through ONNX Runtime Web reads the visual zone with no API key, and face-api.js crops the portrait. Everything runs client-side; the only network dependency is the SDK engine and its models, about 12.8 MB on the first capture.
What you’ll build: A browser page that accepts a passport photo from a file, a drag-and-drop, the clipboard or a webcam snapshot, then returns the MRZ as two lines plus the 24 named fields the parser returns with their mapping and validation status, an OCR dump of the visual zone that skips the MRZ band, and a cropped portrait — all without a server.
Key Takeaways
CaptureVisionRouter.capture(image, "ReadMRZ")returns the MRZ text and the parsed fields in one call:itemsholds aCRIT_TEXT_LINEitem and aCRIT_PARSED_RESULTitem, andparsedResult.parsedResultItems[0]exposes 24 field names.- The 3.6.5000 JavaScript bundle ships no MRZ preset template.
EnumPresetTemplatelists 17 values for barcodes, text lines and document boundaries; a passport scanner must supply its ownCaptureVisionTemplate. initSettings()replaces the template table. After loading a custom MRZ template,PT_DETECT_DOCUMENT_BOUNDARIESfails with-10036 EC_TEMPLATE_NAME_INVALIDunless the document templates live in the same settings object.- In the JavaScript edition
getFieldValue()resolves leaf names (passportNumber); the dotted paths returned bygetAllFieldNames()(line2.passportNumber) returnnull. - Measured on five passport pages: four read exactly, one returned a single wrong character at confidence 97. ICAO 9303 check digits cover the number, dates and personal number — never the name, so a passing checksum does not mean a correct name.
- The first
capture()costs about 8 s because the engine WASM (10.1 MB) and the MRZ models (2.7 MB) download on demand; later calls take 176–250 ms depending on the input.
Common Developer Questions
How do I read a passport MRZ in the browser with JavaScript?
Call cvr.capture(dataUrl, "ReadMRZ") with a CaptureVisionTemplate that names the MRZ models, then filter result.items by CRIT_TEXT_LINE for the raw lines and read result.parsedResult.parsedResultItems[0] for the fields. On a 768 × 1024 page the call takes about 180 ms once the engine is warm.
Does Dynamsoft Capture Vision for JavaScript include a built-in MRZ template?
No. EnumPresetTemplate in dynamsoft-capture-vision-bundle 3.6.5000 contains 17 presets — ReadBarcodes_Default, ReadSingleBarcode, ReadDenseBarcodes, ReadDistantBarcodes, the three speed/read-rate variants, RecognizeTextLines_Default, the five character-set presets, DetectDocumentBoundaries_Default, DetectAndNormalizeDocument_Default and NormalizeDocument_Default. None of them reads MRZ; the mobile bundles ship a separate MRZ product, the JavaScript bundle does not.
Why does one passport page return two items from capture()?
The template’s SemanticProcessingNameArray runs a CodeParserTaskSetting, so the same call emits a CRIT_TEXT_LINE item (type 4) with the recognised line and a CRIT_PARSED_RESULT item (type 32) with the structured fields. result.parsedResult.parsedResultItems holds the same parsed item, which is the more convenient entry point.
Do I need to create a CodeParser and call parse() myself?
No, when the template already declares sp-mrz. Calling CodeParser.parse() again on text the template produced returns the same fields and adds no validation. A separate CodeParser instance is only needed when the MRZ string comes from somewhere else — manual keyboard entry, or an OCR engine other than Dynamsoft’s.
Why does getFieldValue(‘line2.passportNumber’) return null?
The JavaScript ParsedResultItem resolves leaf names: getFieldValue('passportNumber') works, the dotted path fails. Use getAllFieldNames() to enumerate the hierarchy (it returns line1.name.primaryIdentifier style paths for display), and the leaf segment for lookups.
How accurate is MRZ recognition on real passport photos?
In this test set of five pages, four returned all 88 characters exactly and one returned a single wrong character at confidence 97 — CALLIE read as CALLDE. Three degradations also failed cleanly: a 6 px Gaussian blur, a 215 × 286 downscale and a clipped MRZ band each returned zero items. The measured table below lists every case with its timing.
How do I extract the passport photo with JavaScript?
Run face-api.js with the SSD MobileNetV1 weights, call detectSingleFace(imageElement), and crop detection.box onto a canvas. On the 768 × 1024 specimen the detector returned a 79 × 121 px box at score 0.985 in 208 ms, which matches the printed portrait.
Can I run passport OCR without an API key?
Yes. PaddleOCR’s PP-OCRv4 detection and recognition models run through ONNX Runtime Web, 15.5 MB of ONNX files served from your own origin. No key, no upload, no quota. Read lines come back as text strings on a tightly cropped page; if the document fills only part of the frame the sample’s small post-processing step returns character-sized boxes instead. Common Issues explains why.
The finished page, running all three stages on one photo:
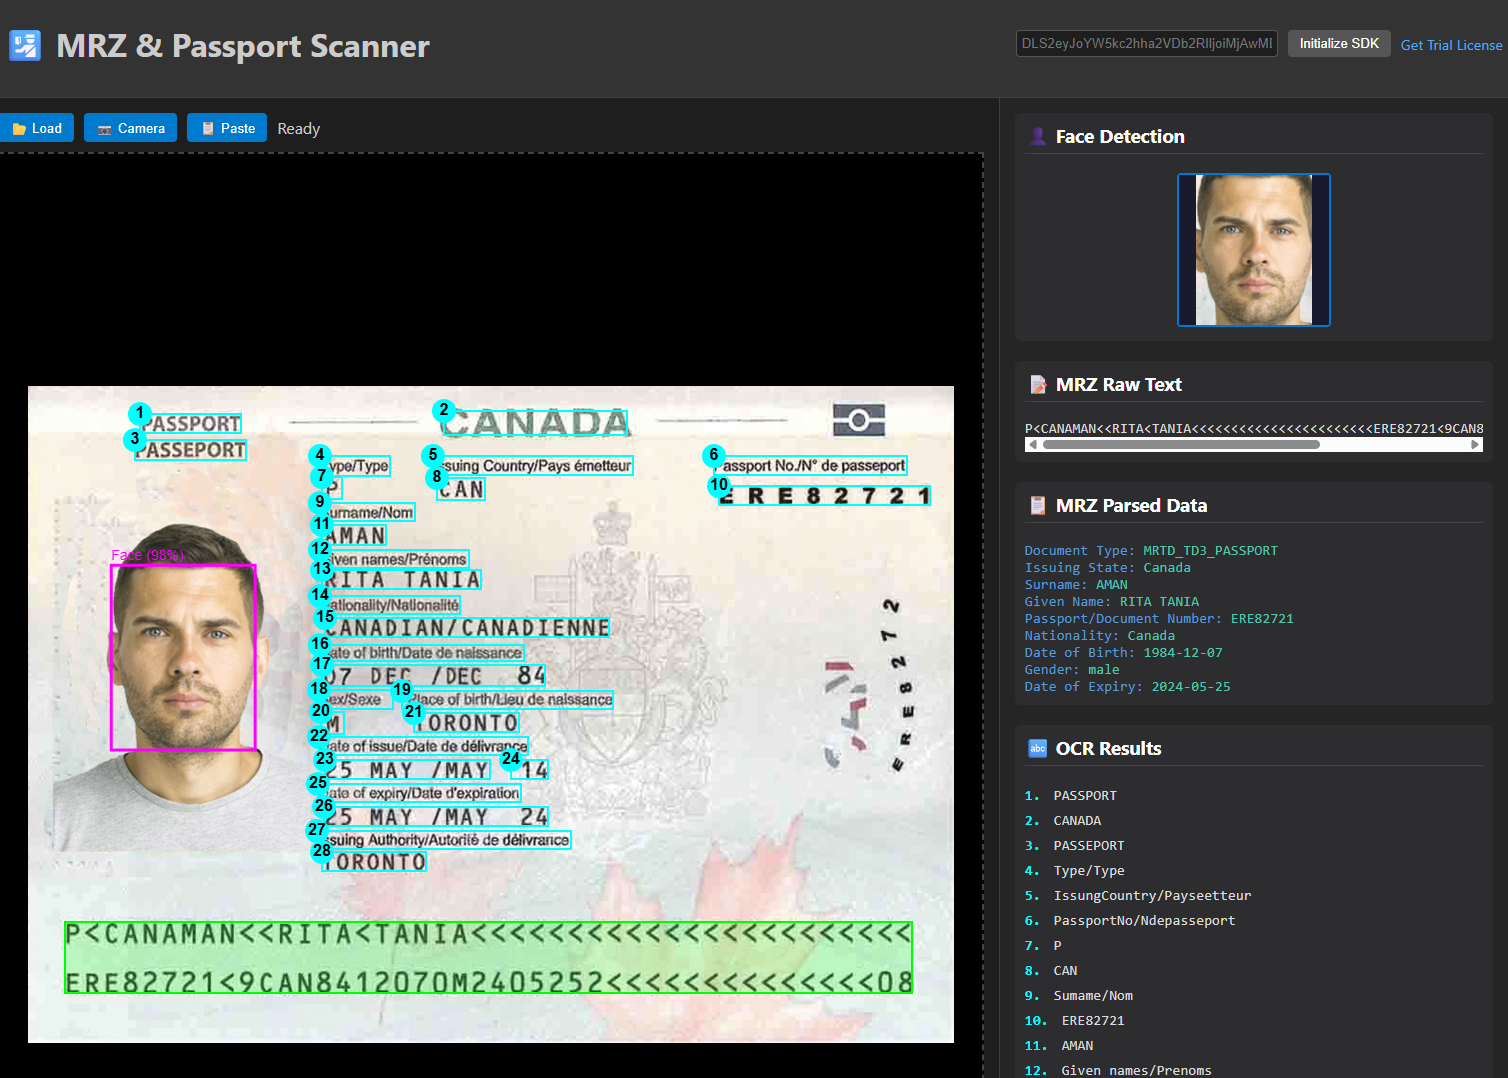
Watch the MRZ Scanner and Face Detection Run Live in a Browser
Online Demo
https://yushulx.me/javascript-barcode-qr-code-scanner/examples/mrz_solution/
The Minimal MRZ Path
Three calls, no wrapper class. This is the entire MRZ pipeline; the OCR and portrait stages later in the article are application code around it.
// 1. Activate the SDK. MRZ is a licensed capability.
await Dynamsoft.License.LicenseManager.initLicense(licenseKey, true);
await Dynamsoft.Core.CoreModule.loadWasm();

// 2. One router, configured with a template that names the MRZ models.
const cvr = await Dynamsoft.CVR.CaptureVisionRouter.createInstance();
const info = await cvr.initSettings("./full.json");   // defines the template "ReadMRZ"
if (info.errorCode !== 0) throw new Error(info.errorString);

// 3. One call returns the raw lines AND the parsed fields.
const result = await cvr.capture(dataUrl, "ReadMRZ");

const line   = result.items.find(i => i.type === Dynamsoft.Core.EnumCapturedResultItemType.CRIT_TEXT_LINE);
const parsed = result.parsedResult?.parsedResultItems?.[0];

console.log(line.text);                                  // 88 characters, both MRZ lines joined
console.log(line.confidence);                            // 97
console.log(parsed.getFieldValue("passportNumber"));     // "ERE82721"
console.log(parsed.getFieldValue("secondaryIdentifier")); // "RITA TANIA"
Two details in that snippet are easy to get wrong. loadWasm() takes no module list in the 3.x bundle and returns in under a millisecond — the engine WASM and the MRZ models load lazily during the first capture(), which is why the first scan takes seconds and the second takes milliseconds. And "ReadMRZ" is not a preset; it is a template name defined in the settings file, so initSettings() must succeed before the first capture.
What the ReadMRZ Template Must Contain
Because the JavaScript bundle has no MRZ preset, the template file does the work that the mobile SDKs hide behind MRZScanner. Five blocks in full.json matter:
| Block | Name in full.json |
Role |
|---|---|---|
TextLineSpecificationOptions |
tls-mrz-passport, tls-mrz-visa-td3, tls-mrz-id-td1, tls-mrz-id-td2, tls-mrz-visa-td2 |
Fix the accepted line length (44, 44, 30, 36, 36) and a per-line regex, so only MRZ-shaped text survives recognition |
LabelRecognizerTaskSettingOptions |
task-mrz |
Runs region predetection, text-line localisation and recognition with MRZCharRecognition and MRZTextLineRecognition |
SemanticProcessingOptions |
sp-mrz |
Hands the recognised lines to the code parser |
CodeParserTaskSettingOptions |
dcp-mrz |
Declares the five MRTD specs to try — this is what replaces CodeParserModule.loadSpec() |
CaptureVisionTemplates |
ReadMRZ |
Binds the four blocks above under the name you pass to capture() |
The binding itself is four lines, and it is the only part you edit:
{
  "ImageROIProcessingNameArray": ["roi-mrz"],
  "Name": "ReadMRZ",
  "SemanticProcessingNameArray": ["sp-mrz"],
  "Timeout": 1000000
}
roi-mrz points at task-mrz; sp-mrz points at dcp-mrz. Break either link and capture() returns errorCode: 0 with an empty items array — no exception, no message. The CodeParserTaskSetting is what makes the second item appear: as long as it lists MRTD_TD3_PASSPORT and its siblings, you never call CodeParserModule.loadSpec() yourself. A page that never touches Dynamsoft.DCP still returns all 24 parsed fields.
The file is 507 lines because it also carries a VIN template (ReadVINText) that this scanner does not use; the MRZ half is the five blocks above.
Expected Result Object
This is the payload from the 768 × 1024 Canadian specimen, trimmed to the fields that matter:
{
  errorCode: 0,
  errorString: "Successful.",
  items: [
    {
      type: 4,                          // CRIT_TEXT_LINE
      text: "P<CANAMAN<<RITA<TANIA<<<<<<<<<<<<<<<<<<<<<<<ERE82721<9CAN8412070M2405252<<<<<<<<<<<<<<08",
      confidence: 97,                   // 0-100
      location: {
        points: [ {x: 97, y: 779}, {x: 631, y: 782}, {x: 635, y: 826}, {x: 96, y: 826} ]
      }
    },
    {
      type: 32,                         // CRIT_PARSED_RESULT
      codeType: "MRTD_TD3_PASSPORT",
      jsonString: "{ \"CodeType\": \"MRTD_TD3_PASSPORT\", \"ResultInfo\": [ ... ] }"
    }
  ],
  parsedResult: {
    parsedResultItems: [ /* the same ParsedResultItem as items[1] */ ]
  }
}
items[0].text is 88 characters, both MRZ lines concatenated with no separator — not two lines and not newline-delimited. Join every CRIT_TEXT_LINE item, then split at 44 for display:
const display = line.text.match(/.{1,44}/g).join("\n");
getAllFieldNames() returns 24 entries for a TD3 passport, including the parent nodes:
line1  line1.documentCode  line1.issuingState  line1.name
line1.name.primaryIdentifier  line1.name.secondaryIdentifier
line2  line2.passportNumber  line2.checkDigitForPassportNumber  line2.nationality
line2.dateOfBirth  line2.dateOfBirth.birthYear  line2.dateOfBirth.birthMonth  line2.dateOfBirth.birthDay
line2.checkDigitForBirthDate  line2.sex
line2.dateOfExpiry  line2.dateOfExpiry.expiryYear  line2.dateOfExpiry.expiryMonth  line2.dateOfExpiry.expiryDay
line2.checkDigitForExpiryDate  line2.personalNumber  line2.checkDigitForPersonalNumber  line2.compositeCheckDigit
Read the fields with the leaf name and pick the getter that matches the job:
| Field | getFieldValue() |
getFieldRawValue() |
Mapping | Validation |
|---|---|---|---|---|
documentCode |
P |
P< |
— | passed |
issuingState |
Canada |
CAN |
succeeded | passed |
primaryIdentifier |
AMAN |
AMAN |
— | failed |
secondaryIdentifier |
RITA TANIA |
<<RITA<TANIA<<<<<<<<<<<<<<<<<<<<<<< |
— | failed |
passportNumber |
ERE82721 |
ERE82721< |
— | passed |
nationality |
Canada |
CAN |
succeeded | passed |
dateOfBirth |
841207 |
841207 |
— | passed |
sex |
male |
M |
succeeded | passed |
dateOfExpiry |
240525 |
240525 |
— | passed |
personalNumber |
(empty) | <<<<<<<<<<<<<< |
— | passed |
compositeCheckDigit |
8 |
8 |
— | passed |
Three rules follow from that table. getFieldValue() returns the mapped value where the spec defines one, so sex is male, not M, and nationality is Canada, not CAN; store getFieldRawValue() if you need the printed code. A field with no check digit — every name field — reports VS_FAILED on getFieldValidationStatus(), which is normal and not a read error. And when the mapping fails the value falls back to the raw string: the US specimen’s issuing state came back as NEL with MS_FAILED, because NEL is not an assigned code.
Real Document Test Cases
Five passport pages, three runs each, median of the three, headless Edge 157 on Windows 11. “Exact” means all 88 characters match the printed MRZ.
| Document | Pixels | Median | Items | Confidence | Result |
|---|---|---|---|---|---|
| Canadian specimen, upright | 768 × 1024 | 176.3 ms | text + parsed | 97 | exact |
| Same page, rotated ≈23° in plane | 768 × 1024 | 729.5 ms | text + parsed | 96 | exact |
| US specimen, 640 px wide | 640 × 441 | 175.9 ms | text + parsed | 97 | 1 character wrong |
| US specimen, generated page | 640 × 441 | 181.8 ms | text + parsed | 96 | exact |
| Canadian specimen, 640 px wide | 640 × 853 | 249.9 ms | text + parsed | 95 | exact |
Four of five are usable as-is. The failure is worth looking at closely, because it is the kind that passes every automated gate.
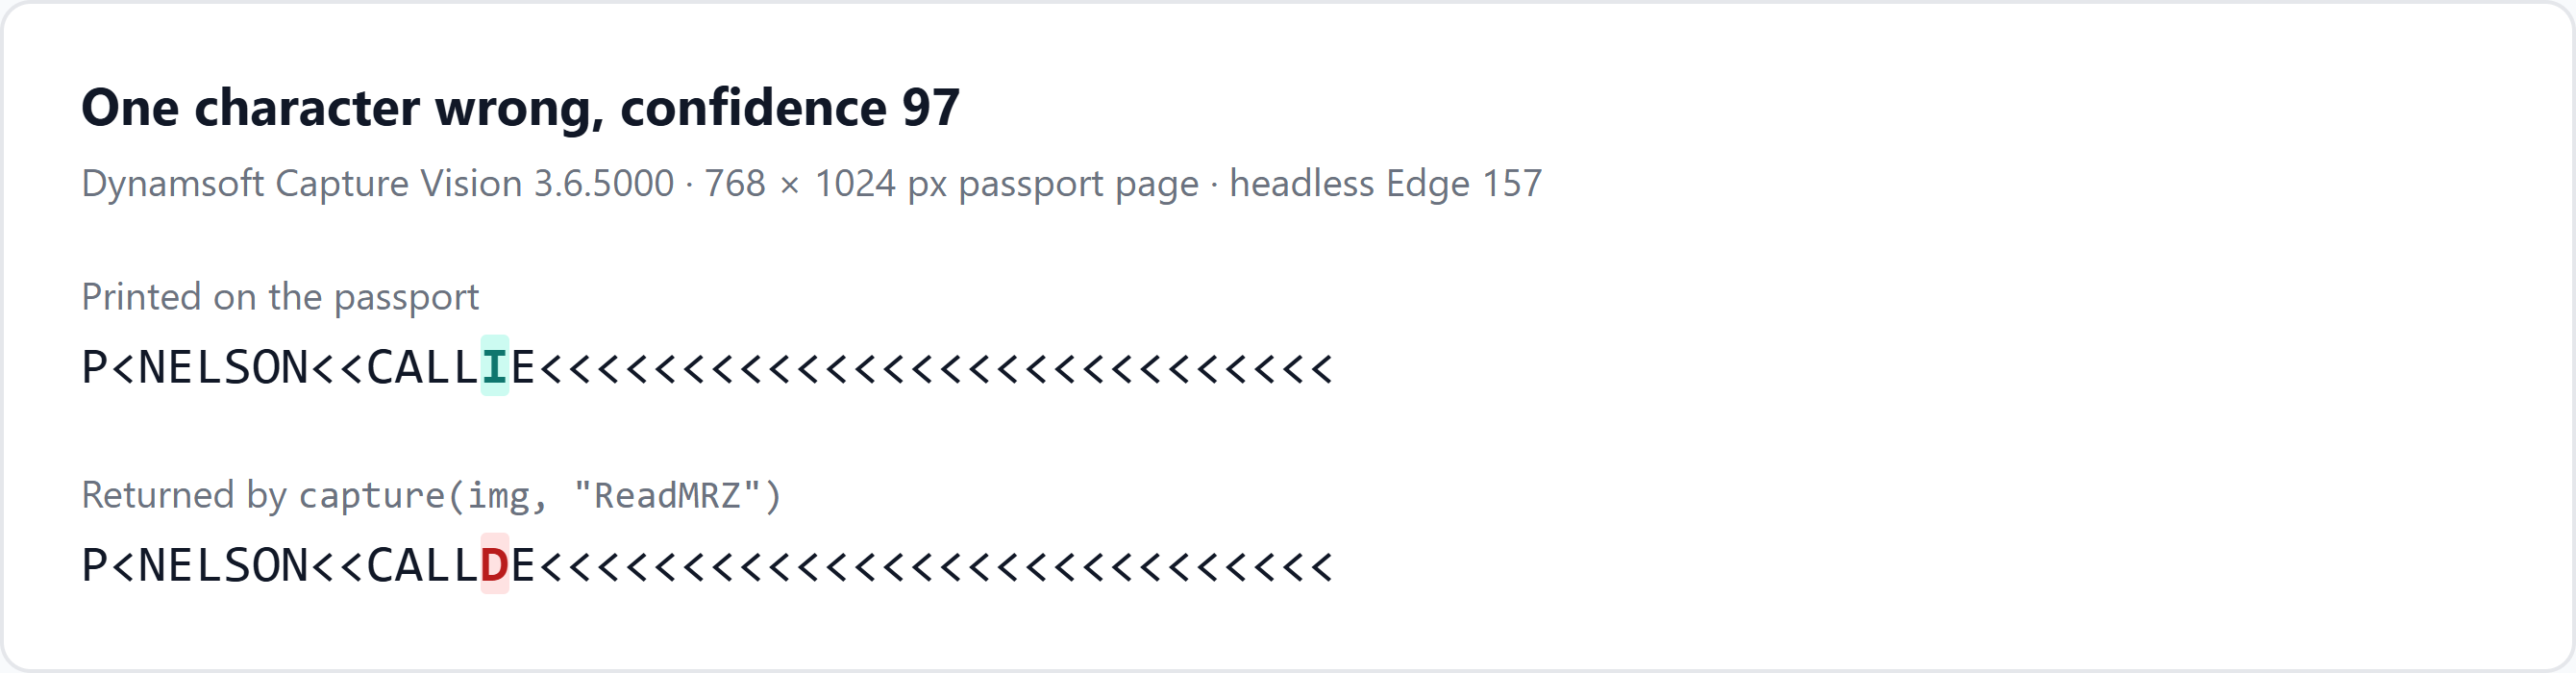
The printed name is CALLIE; the engine returned CALLDE. Confidence 97 — the highest score in the table. Every check digit on line 2 validated: passportNumber, dateOfBirth, dateOfExpiry, personalNumber and the composite digit all report VS_SUCCEEDED, because ICAO 9303 computes those digits over the number, the dates and the personal number. The name carries no check digit, so a single character error there is invisible to checksum validation.
The practical consequence: an integration that gates on errorCode === 0, or on “all check digits passed”, will accept a wrong name. Show the raw MRZ line next to the parsed name so a human can compare, and treat the name as needing corroboration rather than as verified data.
Degradations behave the way a browser scanner needs them to — they fail fast and empty rather than guessing:
| Input | Median | Items | Result |
|---|---|---|---|
| Gaussian blur, σ = 6 px | 27.0 ms | none | no read |
| Downscaled to 215 × 286 | 18.0 ms | none | no read |
| Contrast reduced to 0.35× | 197.2 ms | text + parsed | exact |
| Bottom 22% cropped, MRZ removed | 88.3 ms | none | no read |
| No document in frame | 22.2 ms | none | no read |
A successful read costs 176–730 ms here; every failure returns in 18–88 ms. If your scanner answers in 20 ms, it has not found a text line, and that is an early exit rather than a fast decode — do not read it as performance. Low contrast is tolerated; blur, resolution loss and a clipped MRZ band are not, and the cropped case is the one to guard against in UI: removing the bottom 22% of a 1024 px page was enough to lose the whole MRZ.
Which Stage Owns Each Job
The three capabilities are independent, and only one of them is a Capture Vision template. This is what each call actually returns:
| Stage | Call | Returns | Licence | Measured |
|---|---|---|---|---|
| MRZ recognition | capture(img, "ReadMRZ") — label recognizer + code parser |
one CRIT_TEXT_LINE and one CRIT_PARSED_RESULT |
Capture Vision | 176 ms flat, 730 ms skewed |
| Document boundaries | capture(img, PT_DETECT_DOCUMENT_BOUNDARIES) |
a single CRIT_DETECTED_QUAD, four corners |
Capture Vision | found the page on all three test images |
| Detect and normalise | capture(img, PT_DETECT_AND_NORMALIZE_DOCUMENT) |
quad + CRIT_DESKEWED_IMAGE + CRIT_ENHANCED_IMAGE |
Capture Vision | 72–75 ms |
| Portrait | faceapi.detectSingleFace(img) — face-api.js |
box {x, y, width, height} |
MIT, free | 208 ms warm, score 0.985 |
| Visual-zone text | PaddleOCR PP-OCRv4 via ONNX Runtime Web | {box, text}[] |
free, 15.5 MB of models | see Common Issues |
| Overlay and controls | your canvas and DOM | — | — | — |
The constraint that bites is the one listed third in Key Takeaways: initSettings() replaces the whole template table, so a page that loads full.json loses DetectDocumentBoundaries_Default and gets -10036 if it tries to use it. Keep both sets in one settings object:
const mrz = await (await fetch("./full.json")).json();
const presetUrl = "https://cdn.jsdelivr.net/npm/dynamsoft-capture-vision-data@1.2.2/templates/DDN-PresetTemplates.json";
const ddn = await (await fetch(presetUrl)).json();   // the document templates

const settings = {};
for (const src of [mrz, ddn]) {
  for (const [key, value] of Object.entries(src)) {
    if (Array.isArray(value)) {
      settings[key] = [...(settings[key] || []), ...value];
    } else {
      settings[key] = { ...(settings[key] || {}), ...value };
    }
  }
}
await cvr.initSettings(settings);
With those merged settings, DetectDocumentBoundaries_Default returned the page quad on all three test images and DetectAndNormalizeDocument_Default returned [8, 16, 64] — quad, deskewed image, enhanced image.
Whether to normalise before reading is a measurable decision, not a stylistic one:
| Input | MRZ directly | Normalise, then MRZ |
|---|---|---|
| Upright page, 768 × 1024 | 176.3 ms | 74.7 + 163.2 = 240.9 ms |
| Same page rotated ≈23° | 729.5 ms | 72.0 + 167.0 = 239.0 ms |
Normalising costs 65 ms on a page that was already upright, and saves 490 ms on the rotated one — because a skewed text line makes the recogniser search every angle. If your input comes from a phone camera, pay for the normalisation; if it comes from a flatbed scan, skip it.
Tested Environment
| Item | Value |
|---|---|
| Browser | Headless Edge 157.0.0.0 (Chromium 157), Windows 11 build 26200 |
| SDK | dynamsoft-capture-vision-bundle 3.6.5000, loaded from jsDelivr |
| Models | dynamsoft-capture-vision-data 1.2.2 — MRZCharRecognition.data, MRZTextLineRecognition.data, MRTD.data |
| Licence | 24-hour public trial key shipped in the sample; requires network on first activation |
| ONNX Runtime Web | 1.18.0 — pinned by the sample to avoid SIMD and threaded-WASM issues |
| face-api.js | 0.22.2, SSD MobileNetV1 weights, 5.6 MB |
| PaddleOCR | PP-OCRv4 det + rec ONNX, 15.5 MB |
| Test images | 5 passport pages, 640 × 441 to 768 × 1024 |
| Not verified | Safari, Firefox, mobile browsers, live camera capture on a device |
The MRZ numbers come from a page that calls capture() directly, not from the UI, so they exclude overlay drawing and DOM work. On first load the SDK also injects a licence notification dialog when the 24-hour public key is used; a normal 30-day trial key does not trigger it.
Prerequisites
- A browser with WebAssembly — Chrome 113+, Edge 113+ or Firefox 116+. The OCR code requests WebGPU and falls back to WASM when the backend is missing, which is what happens in headless Chromium.
- Dynamsoft Capture Vision licence — MRZ recognition is a licensed capability. Get a 30-day free trial license and paste the key into the page.
- ONNX Runtime Web 1.18.0 — loaded from CDN, pinned; leave it pinned.
- face-api.js 0.22.2 — loaded from CDN.
- PaddleOCR models —
ch_PP-OCRv4_det.onnx,ch_PP-OCRv4_rec.onnxandppocr_keys_v1.txtfrom the sample repository. - face-api.js weights — the SSD MobileNetV1 shards from the same
assets/face-api-models/folder.
Step 1: Build the Two-Panel Page
Create index.html. The element ids matter: the scripts look up placeholderText, mrzRawText, mrzResults, ocrResults, faceCropCanvas, overlayCanvas, btnPaste and googleKeyContainer by name, and a missing id throws a null-property error the first time the script touches it.
<!DOCTYPE html>
<html lang="en">
<head>
<meta charset="UTF-8">
<meta name="viewport" content="width=device-width, initial-scale=1.0">
<title>MRZ & Passport Scanner</title>
<link rel="stylesheet" href="style.css">
<script src="https://cdn.jsdelivr.net/npm/dynamsoft-capture-vision-bundle@3.6.5000/dist/dcv.bundle.min.js"></script>
<script src="https://cdn.jsdelivr.net/npm/onnxruntime-web@1.18.0/dist/ort.min.js"></script>
<script defer src="https://cdn.jsdelivr.net/npm/face-api.js@0.22.2/dist/face-api.min.js"></script>
</head>
<body>
<div class="app-container">
<header>
<h1>MRZ & Passport Scanner</h1>
<div class="license-bar">
<input type="text" id="licenseKey" placeholder="Dynamsoft License Key">
<button id="initBtn">Initialize MRZ</button>
<a href="https://www.dynamsoft.com/customer/license/trialLicense/?product=dcv&package=cross-platform"
target="_blank" rel="noopener noreferrer" class="trial-link">Get MRZ License</a>
</div>
<div class="config-bar">
<label for="ocrEngineSelect">OCR Engine:</label>
<select id="ocrEngineSelect">
<option value="paddle">PaddleOCR (Local)</option>
<option value="google">Google OCR (Cloud)</option>
</select>
<span id="googleKeyContainer" style="display:none;">
<input type="text" id="googleApiKey" placeholder="Google Cloud Vision API Key (Optional)">
</span>
</div>
</header>
<main>
<section class="panel left-panel">
<div class="toolbar">
<button id="btnLoad" disabled>Load</button>
<button id="btnCamera" disabled>Camera</button>
<button id="btnPaste" disabled>Paste</button>
<span id="status">Ready</span>
</div>
<div class="viewer-container" id="dropZone">
<div id="cameraView" class="hidden"></div>
<div id="imageView" class="hidden">
<img id="displayImage" src="" alt="Input">
<canvas id="overlayCanvas"></canvas>
</div>
<div class="placeholder-text" id="placeholderText">
Drag & Drop Image Here<br>or Select Source
</div>
</div>
</section>
<section class="panel right-panel">
<div class="result-group">
<h3>Face Detection</h3>
<div class="face-container"><canvas id="faceCropCanvas" width="150" height="150"></canvas></div>
</div>
<div class="result-group">
<h3>MRZ Raw Text</h3>
<div id="mrzRawText" class="data-box">Waiting for scan...</div>
</div>
<div class="result-group">
<h3>MRZ Parsed Data</h3>
<div id="mrzResults" class="data-box">Waiting for scan...</div>
</div>
<div class="result-group">
<h3>OCR Results</h3>
<div id="ocrResults" class="data-box">Waiting for scan...</div>
</div>
</section>
</main>
</div>
<div id="loadingSpinner" class="spinner-overlay"><div class="spinner"></div></div>
<script src="ocr-processor.js"></script>
<script src="face-processor.js"></script>
<script src="script.js"></script>
</body>
</html>
The sample’s copy uses the same layout: icon glyphs on the buttons and the 24-hour public key pre-filled as the placeholder, so the demo runs without setup.
Step 2: Style the Viewer and the Overlay Canvas
The full stylesheet is 264 lines of theme, and none of it changes the result. What does matter is the handful of rules that keep the overlay aligned with the image, because the canvas is sized to the image’s natural pixels while CSS scales both to the container:
.hidden { display: none !important; }

.viewer-container {
    flex: 1;
    position: relative;
    display: flex;
    justify-content: center;
    align-items: center;
    background: #000;
    overflow: hidden;
}

#imageView { position: relative; width: 100%; height: 100%; }

#displayImage {
    display: block;
    width: 100%;
    height: 100%;
    object-fit: contain;
}

#overlayCanvas {
    position: absolute;
    inset: 0;
    width: 100%;
    height: 100%;
    object-fit: contain;
    pointer-events: none;
}

.data-box {
    font-family: Consolas, monospace;
    font-size: 0.9em;
    white-space: pre-wrap;
    overflow-x: auto;
}
object-fit: contain on both elements is the whole contract: the canvas backing store is set to naturalWidth × naturalHeight in resizeCanvas(), and because image and canvas have the same intrinsic ratio, the browser scales them by the same factor and letterboxes them into the same box. Draw in image pixels; no transform is needed. Replace contain with cover and every box drifts.
Grab the rest of the theme from style.css rather than retyping it.
Step 3: Add Free In-Browser OCR with PaddleOCR
Create ocr-processor.js. Two ONNX sessions — a detection model that finds text lines and a recognition model that reads them — plus a character dictionary:
class OCRProcessor {
    constructor() {
        this.detSession = null;
        this.recSession = null;
        this.isInitialized = false;
        this.characters = null;
    }

    async init() {
        try {
            const options = {
                executionProviders: ['webgpu', 'wasm'],
                graphOptimizationLevel: 'all'
            };

            // Load PaddleOCR detection model
            this.detSession = await ort.InferenceSession.create(
                './assets/ch_PP-OCRv4_det.onnx',
                options
            );

            // Load recognition model
            this.recSession = await ort.InferenceSession.create(
                './assets/ch_PP-OCRv4_rec.onnx',
                options
            );

            // Load character dictionary
            const response = await fetch('./assets/ppocr_keys_v1.txt');
            const text = await response.text();
            this.characters = ['blank', ...text.split('\n').filter(c => c), ' '];

            this.isInitialized = true;
            console.log("✅ PaddleOCR initialized");
        } catch (e) {
            console.error("Failed to initialize OCR:", e);
        }
    }

    async run(imageElement, ocrResultsDiv, canvasOverlay, mrzZone, engine = 'paddle', apiKey = '') {
        if (engine === 'google') {
            return await this.runGoogleOCR(imageElement, ocrResultsDiv, canvasOverlay, mrzZone, apiKey);
        }

        // PaddleOCR local processing
        if (!this.isInitialized) {
            ocrResultsDiv.textContent = "OCR not initialized.";
            return [];
        }

        const boxes = await this.detectText(imageElement);
        const results = [];

        for (const box of boxes) {
            if (mrzZone && this.overlapsWithMrz(box, mrzZone)) continue;

            const text = await this.recognizeText(imageElement, box);
            if (text?.trim()) {
                results.push({ box, text });
            }
        }

        this.drawOverlays(canvasOverlay, results);
        this.displayResults(ocrResultsDiv, results);
        return results;
    }

    async runGoogleOCR(imageElement, ocrResultsDiv, canvasOverlay, mrzZone, apiKey) {
        try {
            let base64Image = imageElement.src.split(',')[1];

            const url = apiKey
                ? `https://vision.googleapis.com/v1/images:annotate?key=${apiKey}`
                : 'https://vision.googleapis.com/v1/images:annotate';

            const response = await fetch(url, {
                method: 'POST',
                headers: { 'Content-Type': 'application/json' },
                body: JSON.stringify({
                    requests: [{
                        image: { content: base64Image },
                        features: [{ type: "TEXT_DETECTION" }]
                    }]
                })
            });

            if (!response.ok) {
                const err = await response.json();
                throw new Error(err.error?.message || 'Google OCR failed');
            }

            const data = await response.json();
            const annotations = data.responses[0].textAnnotations || [];

            const results = [];
            for (let i = 1; i < annotations.length; i++) {
                const ann = annotations[i];
                const vertices = ann.boundingPoly.vertices;

                const box = {
                    x: Math.min(...vertices.map(v => v.x || 0)),
                    y: Math.min(...vertices.map(v => v.y || 0)),
                    width: Math.max(...vertices.map(v => v.x || 0)) - Math.min(...vertices.map(v => v.x || 0)),
                    height: Math.max(...vertices.map(v => v.y || 0)) - Math.min(...vertices.map(v => v.y || 0))
                };

                if (mrzZone && this.overlapsWithMrz(box, mrzZone)) continue;
                results.push({ box, text: ann.description });
            }

            this.drawOverlays(canvasOverlay, results);
            this.displayResults(ocrResultsDiv, results);
            return results;
        } catch (e) {
            console.error("Google OCR Error:", e);
            ocrResultsDiv.textContent = `Google OCR Error: ${e.message}`;
            return [];
        }
    }

    // Additional helper methods: detectText, recognizeText, overlapsWithMrz, etc.
}

const ocrProcessor = new OCRProcessor();

window.initOCR = async function() {
    await ocrProcessor.init();
};

window.runOCR = async function(imageElement, ocrResultsDiv, canvasOverlay, mrzZone, engine, apiKey) {
    return await ocrProcessor.run(imageElement, ocrResultsDiv, canvasOverlay, mrzZone, engine, apiKey);
};
Three things in that file are worth knowing before you tune it. executionProviders: ['webgpu', 'wasm'] asks for WebGPU first; when the backend is unavailable ONNX Runtime logs a warning and continues on WASM, so the same code runs in headless and desktop Chrome. The MRZ zone is passed in and any box overlapping it is skipped, which is why the MRZ never appears twice — once as SDK output and once as OCR noise. And postProcessDetection() is a small connected-component pass rather than PP-OCR’s full DB post-processing; it finds text but does not merge characters into lines, which is the limitation described in Common Issues.
Step 4: Crop the Passport Portrait
Create face-processor.js. SSD MobileNetV1 returns one face box in image pixels, which is exactly the coordinate space the overlay canvas already uses:
let faceDetectionReady = false;

window.initFaceDetection = async function() {
    try {
        await faceapi.nets.ssdMobilenetv1.loadFromUri('./assets/face-api-models');
        faceDetectionReady = true;
        console.log("✅ Face detection ready");
    } catch (e) {
        console.error("Face detection init failed:", e);
    }
};

window.runFaceDetection = async function(imageElement, faceCropCanvas, overlayCanvas) {
    if (!faceDetectionReady) return;

    try {
        const detection = await faceapi.detectSingleFace(imageElement);

        if (detection) {
            const box = detection.box;

            // Draw overlay on main canvas
            const ctx = overlayCanvas.getContext('2d');
            ctx.strokeStyle = '#ff0000';
            ctx.lineWidth = 3;
            ctx.strokeRect(box.x, box.y, box.width, box.height);

            // Crop and display face
            const faceCtx = faceCropCanvas.getContext('2d');
            faceCtx.drawImage(
                imageElement,
                box.x, box.y, box.width, box.height,
                0, 0, faceCropCanvas.width, faceCropCanvas.height
            );
        }
    } catch (e) {
        console.error("Face detection error:", e);
    }
};
detectSingleFace() returns the highest-scoring detection or undefined; a passport page has one portrait, so the single-face API is the right one. The crop uses imageElement as the source with box in natural pixels — do not pass the displayed CSS size, or the crop lands on the wrong region.
Step 5: Initialize the MRZ Pipeline
In script.js, wire the initialize button to the three calls from the minimal path. No CodeParser instance, no loadSpec() calls:
let cvr = null;
let isMRZReady = false;

document.getElementById('initBtn').addEventListener('click', async () => {
    const key = document.getElementById('licenseKey').value.trim();

    try {
        document.getElementById('status').textContent = "Initializing MRZ SDK...";
        await Dynamsoft.License.LicenseManager.initLicense(key, true);

        // 3.x takes no module list here; the engine loads on the first capture.
        await Dynamsoft.Core.CoreModule.loadWasm();

        cvr = await Dynamsoft.CVR.CaptureVisionRouter.createInstance();

        // Loads the custom "ReadMRZ" template, including its MRTD specs.
        const info = await cvr.initSettings("./full.json");
        if (info.errorCode !== 0) throw new Error(info.errorString);

        isMRZReady = true;
        document.getElementById('status').textContent = "MRZ SDK initialized";
        document.getElementById('initBtn').textContent = "MRZ Ready";
        document.getElementById('initBtn').disabled = true;
        document.getElementById('licenseKey').disabled = true;
    } catch (ex) {
        console.error("MRZ init failed:", ex);
        alert("MRZ initialization failed: " + ex.message + "\n\nOCR and face detection still work.");
        document.getElementById('initBtn').disabled = false;
    }
});
The legacy version of this block called CoreModule.loadWasm(["DLR"]), created a CodeParser, and loaded the MRTD specs by hand. All three steps are obsolete in 3.6.5000: loadWasm() accepts no arguments, and the dcp-mrz task setting in full.json already declares the specs, so the parser runs inside capture() whether you create an instance or not. Removing them shortened the path and fixed a real bug — the duplicate parse() call re-parsed text the template had already parsed and returned a second, unvalidated copy of the fields.
Step 6: Run All Three Stages on One Image
Still in script.js. The MRZ runs first because its quad defines the region the OCR must skip; the portrait runs independently.
async function readMrz(dataUrl) {
    if (!isMRZReady || !cvr) return null;

    const result = await cvr.capture(dataUrl, "ReadMRZ");
    const line = result.items.find(
        i => i.type === Dynamsoft.Core.EnumCapturedResultItemType.CRIT_TEXT_LINE
    );
    if (!line) return null;

    return {
        text: line.text,                                   // 88 chars, both lines joined
        confidence: line.confidence,
        points: line.location ? line.location.points : null,
        item: result.parsedResult?.parsedResultItems?.[0] ?? null
    };
}

// Union of every MRZ line quad, used to keep OCR off the MRZ band.
function mrzZoneOf(points) {
    const xs = points.map(p => p.x);
    const ys = points.map(p => p.y);
    return {
        x: Math.min(...xs),
        y: Math.min(...ys),
        width: Math.max(...xs) - Math.min(...xs),
        height: Math.max(...ys) - Math.min(...ys)
    };
}

async function loadImage(dataUrl) {
    const image = document.getElementById('displayImage');
    const overlay = document.getElementById('overlayCanvas');

    image.onload = async () => {
        overlay.width = image.naturalWidth;
        overlay.height = image.naturalHeight;
        document.getElementById('loadingSpinner').classList.add('visible');

        try {
            const mrz = await readMrz(dataUrl);
            let mrzZone = null;

            if (mrz) {
                document.getElementById('mrzRawText').textContent =
                    mrz.text.match(/.{1,44}/g).join("\n");     // two lines, not one 88-char run
                if (mrz.item) displayParsedMrz(mrz.item);
                if (mrz.points) {
                    drawOverlay(mrz.points);                   // green quad on the canvas
                    mrzZone = mrzZoneOf(mrz.points);
                }
            } else {
                document.getElementById('mrzRawText').textContent = "No MRZ detected.";
            }

            await window.runFaceDetection(image, document.getElementById('faceCropCanvas'), overlay);
            await window.runOCR(
                image,
                document.getElementById('ocrResults'),
                overlay,
                mrzZone,
                document.getElementById('ocrEngineSelect').value,
                document.getElementById('googleApiKey').value.trim()
            );
        } finally {
            document.getElementById('loadingSpinner').classList.remove('visible');
        }
    };

    image.src = dataUrl;   // set after onload so a cached data URL cannot fire first
}
displayParsedMrz(mrz.item) is the same renderer the sample already had — it calls getFieldValue() on leaf names, which the ParsedResultItem supports. Feeding it the template’s own parsed item instead of a second CodeParser result is what removes the duplicate parse.
Step 7: Cache the Models for Offline Use
Create service-worker.js. Cache the 21 MB of model files, not the HTML — during development you want the page to update without a cache purge:
const CACHE_NAME = 'mrz-scanner-models-v1';
const MODEL_ASSETS = [
    './assets/ch_PP-OCRv4_det.onnx',
    './assets/ch_PP-OCRv4_rec.onnx',
    './assets/ppocr_keys_v1.txt',
    './assets/face-api-models/ssd_mobilenetv1_model-weights_manifest.json',
    './assets/face-api-models/ssd_mobilenetv1_model-shard1',
    './assets/face-api-models/ssd_mobilenetv1_model-shard2',
    './full.json'
];

self.addEventListener('install', (event) => {
    event.waitUntil(caches.open(CACHE_NAME).then((cache) => cache.addAll(MODEL_ASSETS)));
});

self.addEventListener('activate', (event) => {
    event.waitUntil(
        caches.keys().then((names) => Promise.all(
            names.filter((n) => n !== CACHE_NAME).map((n) => caches.delete(n))
        ))
    );
});

self.addEventListener('fetch', (event) => {
    if (!new URL(event.request.url).pathname.includes('/assets/')) return;
    event.respondWith(
        caches.match(event.request).then((hit) => hit || fetch(event.request).then((res) => {
            if (res && res.status === 200 && res.type === 'basic') {
                caches.open(CACHE_NAME).then((cache) => cache.put(event.request, res.clone()));
            }
            return res;
        }))
    );
});
Register it from script.js after the page loads. ./full.json belongs in the list: it is small, it defines the template, and without it an offline session fails at initSettings() even though every model is cached. The old list also carried version-RFB-320.onnx, a 1.2 MB model nothing references — it was replaced by the SSD MobileNetV1 weights and is no longer cached.
Common Issues & Edge Cases
-10036 EC_TEMPLATE_NAME_INVALIDafter loadingfull.json:initSettings()replaces the template table instead of extending it, so every preset disappears. Merge the preset JSON into the same settings object, as shown in Which Stage Owns Each Job, or keep a secondCaptureVisionRouterfor document detection.- The first scan takes 8 seconds and the second takes 180 ms: the engine WASM (10.1 MB) and the MRZ models (2.7 MB) download during the first
capture().loadWasm()does not do it — it returns in under a millisecond in 3.x. Run one throwaway capture against a small image at startup and keep the spinner up until it resolves. initLicense()blocks on the network: with the 24-hour public key and an empty licence cache, the call took 19 seconds in this run; a cached licence took 488 ms. Handle the rejection and keep the OCR and portrait stages usable without a licence, which is what the sample’s try/catch does.getFieldValue('line2.passportNumber')returns null: the JavaScript edition resolves leaf names only. UsepassportNumber, and keepgetAllFieldNames()for building the display labels.- The MRZ panel shows one long line instead of two:
items[0].textis 88 characters with both lines concatenated and no separator. Split at 44 characters for display. Double-escaping the newline in the join call emits the two visible characters backslash andninstead of breaking the line, which is what the earlier version of this sample did. - Every name field reports
VS_FAILED: names carry no ICAO 9303 check digit, sogetFieldValidationStatus()fails forprimaryIdentifierandsecondaryIdentifieron a perfectly correct read. Do not use that status as a read-success gate. - A parenthesised country name appears in the output: the spec maps
USAtoUnited States of America (the). StoregetFieldRawValue()when the downstream system expects the three-letter code. - PaddleOCR returns character-sized boxes on a scene photo:
postProcessDetection()thresholds the probability map and runs connected components without the dilation step PP-OCR uses to merge characters into text lines. On a tightly cropped page (640 px wide) the OCR panel returned readable lines —PASSPORT,CANADA,Issuing Country/Paysemetteur,AMAN— but on a 768 × 1024 desk photo, where the passport filled less than half the frame, it returned single letters. Crop to the document or upscale so text lines are roughly 40 px high before recognition; the MRZ stage is reliable at either size, the OCR stage is not.
Conclusion
The MRZ is the part of a passport that can be read with certainty, and the JavaScript bundle gives you exactly one call to do it — provided you supply the template the preset list does not contain. Everything else in the page is separable: document detection and normalisation are separate templates that must share one settings object, the portrait is a face detector, the visual zone is OCR, and the overlay is a canvas that trusts image coordinates. Keeping those boundaries explicit is what makes the result debuggable: when a read fails you know whether the text line was missing, the parse failed, or your own gate rejected a valid read.